Full audit
Brand + 3–5 priority products
4 AI systems · 40–60 buying situations
Full action plan and retest.
Visibility, representation and product selection
Are your products recommended when customers ask AI what to buy?
We test how ChatGPT, Gemini, Perplexity and other relevant AI systems find and recommend your products in the buying situations that matter to your business.
Full audit
Brand + 3–5 priority products
4 AI systems · 40–60 buying situations
Full action plan and retest.
Free product diagnostic
1 product
3 AI systems · 1 buying situation
What we found and what to fix first.
The buying decision
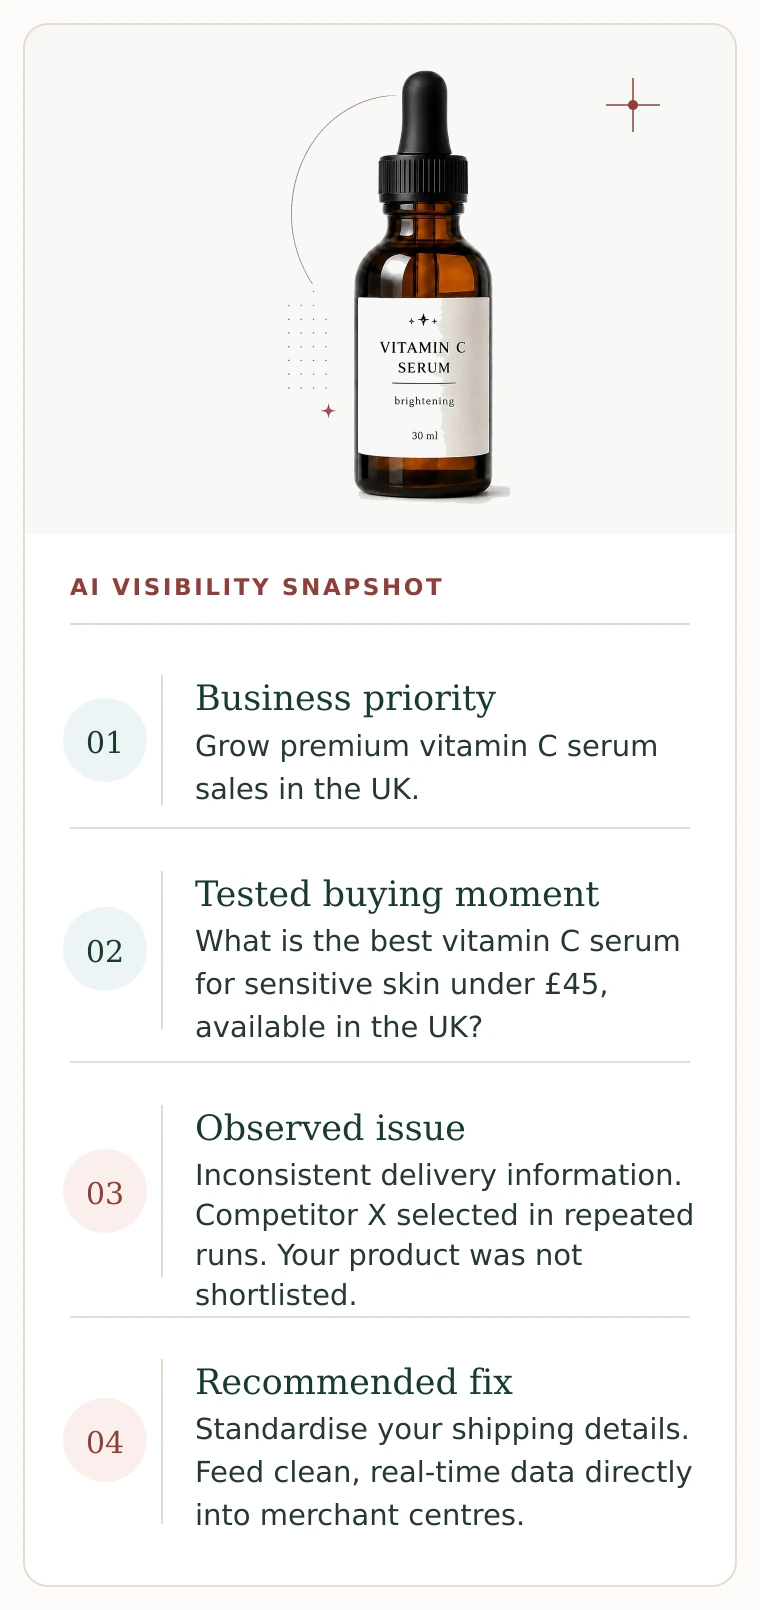
A brand can appear in a broad AI answer and still be absent when a customer asks which product to buy.
At that point, details such as price, availability, delivery, ingredients, suitability and claims can change the answer. Those facts may differ across your site, product feeds, retailers and other sources.
A brand visibility score cannot show whether a specific product was selected, omitted or described accurately. General advice to publish more content cannot identify which product fact or source needs attention.
The audit tests specific buying situations, checks the product and source evidence, and shows what to fix first.

What we do differently
We treat AI as a tool that can support or limit growth, not as a score to chase. We define the product, customer, market and commercial question first, then test the buying situations that matter to that goal.
Step 1 of 5 Follow the audit from commercial objective to testing plan.
Define the growth, market, brand or product question the audit must help answer.
Focus the test on the people and places that matter to your growth plan.
Choose the products, claims and attributes that should influence selection.
Build realistic discovery, comparison and choice questions around the customer.
Agree the systems, markets, languages, competitors, repeat runs and product evidence to verify.
Our tools help us test consistently. Senior review turns the evidence into a business recommendation your team can act on.

What we test
Being mentioned is only one layer. In a buying answer, a product can be selected, omitted, replaced by a competitor, cautioned against or misdescribed. Each outcome calls for a different response.
You see the commercial problem, the evidence behind it and where action is most likely to matter.
Explore: How AI product recommendations differ across systems (blog)
What you get
We show what happened, why it matters, which evidence supports the finding and what your team should address first. You also receive the underlying record so the recommendation can be challenged, shared and retested.
Component 1 of 6 Select any box to focus on one part of the Evidence File.
Where products are found, considered, selected, omitted or replaced.
Who AI selects instead, in which buying situations and what the answer appeared to favour.
Where products are represented accurately, hedged, misdescribed or cautioned against.
What to address first, why it matters, which team owns it and what to do next.
The questions, responses, sources and observations behind every important finding.
Track the priority systems, markets and buying moments your business decided matter after the audit.
You do not leave with another dashboard. You leave knowing what your team should do next.
Inside a full audit
This format shows how an AI answer is compared with product facts and source evidence before a recommendation is made.

Why Lex Agentica
The audit connects AI buying answers with product facts, commercial priorities and the sources that may shape a recommendation.
Pilar Berrío leads the audit. Her 25 years in marketing and ecommerce include senior SEO work. View Pilar’s profile.
Findings are assessed for commercial relevance, so a brand mention is not mistaken for a product recommendation.
Relevant buying situations are tested repeatedly, with an evidence record that can be checked and retested.
The audit compares markets and languages in scope, and flags claim or source gaps that could create trust or governance risks for European brands.
Lex Agentica combines in-house tools, AI-assisted workflows and senior review so the final recommendation is based on evidence, not a single response or automated score. See how product claims intersect with AI recommendations in beauty ecommerce.
Free product diagnostic
We test one product in one realistic buying situation across three relevant AI systems.
You receive what we found, the evidence behind it and what should be fixed first.
1 product. 3 AI systems. 1 buying situation. Not a full audit.
AI Commerce Visibility & Selection Audit
Tell us the commercial question you need to answer. We build the scope around the right products, customers, markets, AI systems, languages, competitors and buying situations, then confirm it with you before any work begins.
Best suited to consumer brands with active e-commerce catalogues, priority European markets and internal teams able to act on cross-functional recommendations.
Test a product insteadAfter the audit
Your internal teams or trusted partners address the product-data, content and source gaps identified in the audit.
We verify whether the relevant visibility, representation or selection behaviour changed after the fixes.
Track the platforms, markets and buying moments your business decided matter.
Optional add-onLex Agentica does not alter your systems or publish changes. We provide the evidence and priorities; your internal teams or trusted partners implement them.
Questions
It shows how AI systems find, describe, compare and recommend your products in the buying situations that matter to your business. It also investigates the gaps that may be limiting selection.
Automated tools can track visibility trends. The audit diagnoses specific product outcomes by testing buying questions, checking the product facts and sources behind the answers, and prioritising the gaps that matter to your business.
There is overlap, but the commercial question is broader for ecommerce. AI SEO, GEO and AEO often focus on mentions, citations or visibility. We also test whether your products are represented correctly, considered and selected as buyers move closer to a decision.
We select the systems that matter to your target audience and markets. This can include ChatGPT, Gemini, Perplexity, Claude and other relevant AI discovery or shopping systems.
A broad answer may name a brand without comparing products. A specific buying question can depend on current price, availability, suitability, claims and source information. The audit checks what happened for the products and markets in scope.
Yes. The scope defines the relevant markets and languages. Results are tested and compared in context, rather than assuming an answer in one language represents another market.
No. The test set is built around your products, target audience, markets and business priorities.
There is no fixed package. Scope depends on the products, markets, AI systems, languages and business questions we need to investigate. We confirm the scope and cost before any work begins.
No. We can show where AI visibility and product selection may be helping or limiting your commercial goals, and what your team should address. We do not claim that an AI recommendation automatically causes a sale.
Your team can implement the priority changes, then Lex Agentica can retest the affected buying situations. Ongoing AI Commerce Monitoring is available as an optional add-on.