The more useful question is not ‘How do we rank in ChatGPT?’ It is: when a buyer asks an AI system what to buy, why does our product appear, disappear or lose to a competitor, and what can we improve?
That matters because one AI answer can influence several parts of the buying decision at once. A product may be discoverable but described incorrectly. It may be represented accurately but never recommended. It may be recommended but lose the final comparison. Or it may be selected while the price, availability or merchant information is wrong.
Those are different problems and they need different fixes. One ‘AI visibility score’ will not tell you where the real issue is.
What ecommerce leaders need to know
- AI product visibility is only the first commercial step. The useful path is visible → represented correctly → recommended → selected → able to progress towards purchase.
- There is no public formula for AI product recommendations. Product data, reviews, price, availability, third-party information and the customer’s request can all matter, but public documentation does not tell us how much weight each system gives them.
- Product data infrastructure matters. OpenAI supports structured product feeds for approved partners, while Google continues to expand Merchant Center product data, AI Performance Insights and conversational attributes.
- Technical optimisation is not enough on its own. Retailer listings, reviews, editorial sources, certifications, independent evidence and local market information can also affect how a product is understood and compared.
- Start with the problem you can see. Is the product absent, described incorrectly, losing to competitors or showing the wrong price? Work from that evidence before investing in broad ‘AI optimisation’.
From being visible to being selected
AI visibility is often measured as if every appearance has the same value. It does not.
- Visible. The product enters the answer, shortlist, carousel or research process for a relevant buying situation.
- Represented correctly. The system gets the product, variant, attributes, claims, price and intended use right in the details that matter.
- Recommended. The product receives a favourable recommendation or is included among plausible choices rather than merely being mentioned.
- Selected. The product becomes the preferred or final choice for the buyer’s stated need, budget and constraints.
- Able to progress towards purchase. The customer can reach a reliable merchant, price, availability, checkout or other next step without the recommendation breaking down.
This is not a fixed funnel. Different AI systems show different parts of the journey. Separating these outcomes helps the team see where the problem starts.
What we have seen in testing
This article builds on Lex Agentica’s own product-recommendation testing. The important point is to keep what we observed separate from what we think it may mean.
In earlier testing, we used real buying questions across categories with very different information needs, including treadmills and baby face cream. For treadmills, the comparison depended heavily on product details such as speed, motor power, running surface, stability, delivery, warranty and price. For baby face cream, trust mattered more, so ingredients, suitability, safety claims, reviews, certifications and local evidence became more important.
The purpose was not to rank platforms or brands. It was to see how different AI systems built a recommendation, what information they used, where they became cautious and what an ecommerce team could investigate.
The product evidence layer
Across those tests, the product page was only one part of the information used in recommendations. We repeatedly encountered product pages, titles, descriptions, images, specifications, reviews, price, availability, retailer listings and structured commerce data. We also saw third-party reviews, comparison articles, certifications, safety evidence, clear product and brand information, and local-language sources become relevant in some buying situations.
Not every system used the same sources in the same way. The weaknesses appeared in different places: product data, external sources, languages, markets and buying situations. A brand may have excellent product pages but weak feeds. It may have strong reviews but vague attributes. It may have recognised brand authority but poor local-market evidence.
What we saw → what to check
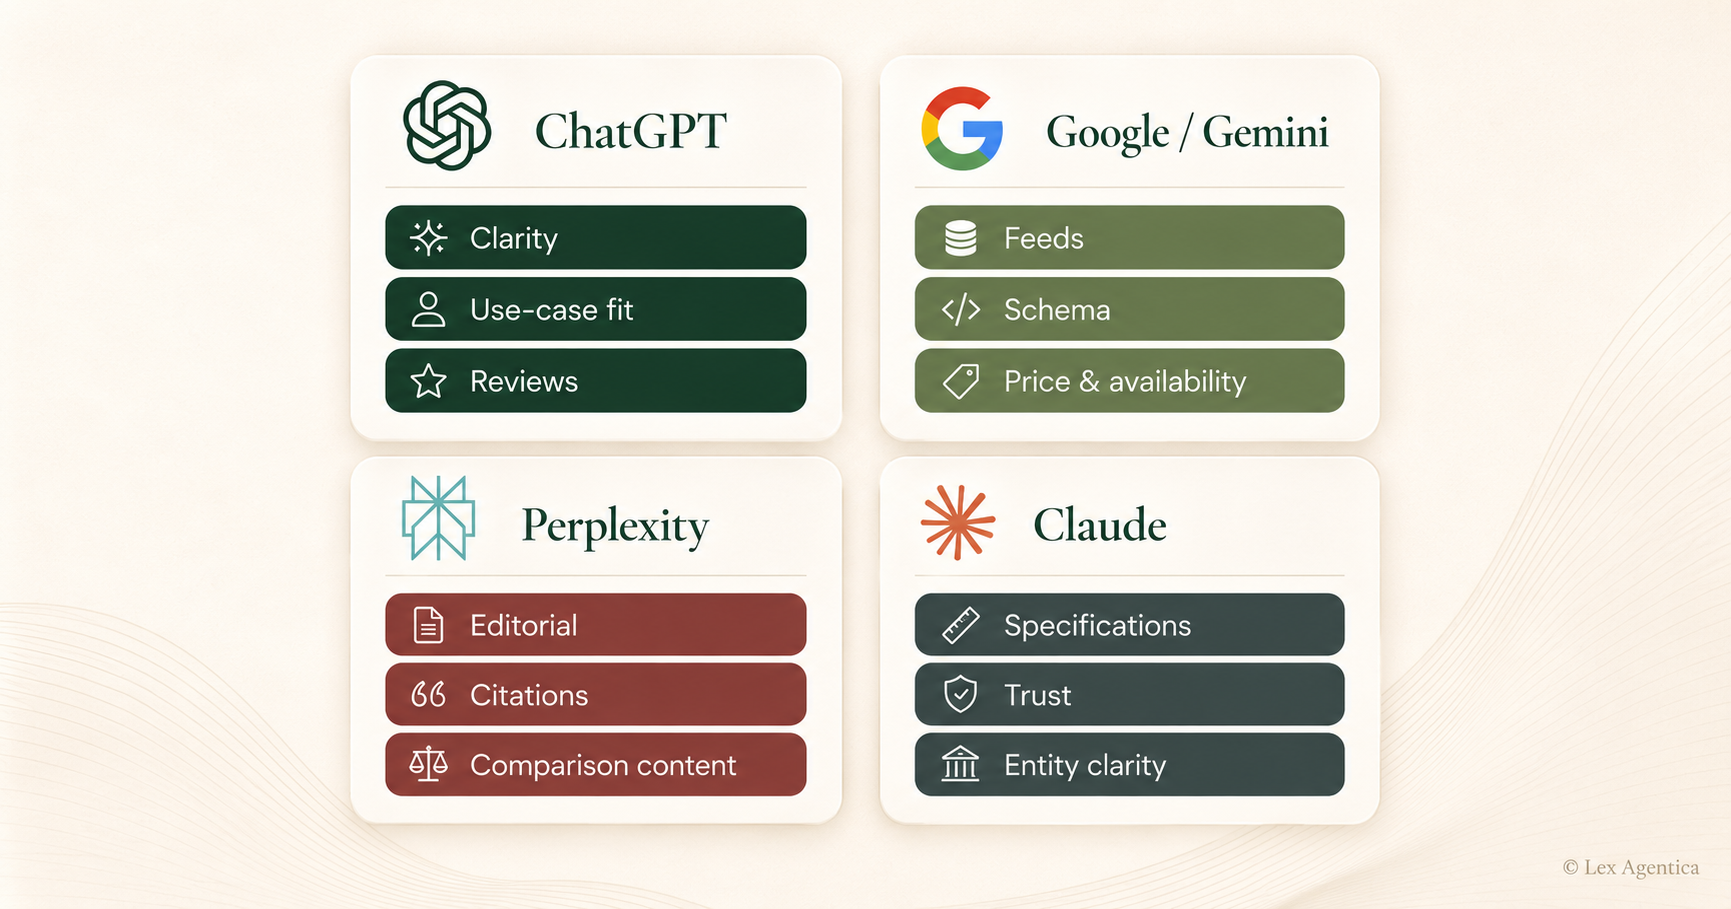
The comparison below shows what appeared repeatedly in our tests, what it may mean and what to check first. It does not tell us how each platform ranks products.
| System | What we saw | What it may mean | Check first |
|---|---|---|---|
| ChatGPT | Shortlists often used clear product attributes, fit for the customer’s need, reviews and product explanations. Vague claims often led to more cautious answers. | Clearer products may be easier for the system to compare and recommend with confidence. | Specifications, use cases, supported claims, reviews, current price and availability. |
| Google & Gemini | Structured product data, local market information and trust-related evidence appeared repeatedly. Claims and safety evidence were especially visible in the baby-care tests. | Product data and supporting evidence may affect how confidently a product is compared. | Merchant Center, attributes, identifiers, structured data, local availability, claims and certifications. |
| Perplexity | Answers frequently relied on editorial reviews, comparison sources and other material they could cite. | If credible third-party evidence is weak, the product may be harder to support in an answer built around sources. | Independent reviews, specialist retailers, expert comparisons and technical explainers. |
| Claude | Answers became more cautious when specifications, the exact product or brand, or sensitive claims were unclear. | Unclear information may lead to a more cautious answer rather than the product simply disappearing. | Specification precision, claim scope, product-level evidence and authoritative support. |
| Across systems | The same buying question could produce different products, sources, warnings and competitor choices. | One prompt or one run is not enough to explain why the result happened. | Repeated runs, source changes, competitor recurrence, framing differences and market variation. |
Use this table to decide what to check first. It does not show how each platform ranks products.
What the platform differences can tell us
ChatGPT: in our earlier product tests, it often behaved like a shopping adviser: it interpreted the need, weighed constraints and explained a shortlist. When product attributes were precise, the reasoning was usually more specific. When claims or specifications were vague, the answer was more likely to hedge. Current OpenAI documentation also shows that product discovery can use merchant data, public product information and other retail sources. The practical question is whether those sources describe the product clearly and consistently.
Google and Gemini: deserve separate attention because Google connects Search, Merchant Center, structured commerce data and AI experiences. In our trust-sensitive baby-care tests, safety language, claims and certification evidence became especially visible. That is consistent with Google’s growing focus on current product data and richer conversational attributes, but it does not tell us how Google weighs those inputs in a recommendation.
Perplexity: often built its answers around sources it could cite in our tests. Products with stronger editorial, review and comparison evidence were easier to support with citations. The useful response is not to chase low-quality listicles. Check whether credible third parties give the system enough information to understand and support the product.
Claude: was useful for showing where information was unclear. When specifications, the exact product or sensitive claims were unclear, answers often became more cautious. That makes it useful for testing categories where claims or suitability need more care, even if the purchase happens elsewhere.
What to do with these findings
Do not start by creating a separate optimisation plan for every platform. Start with accurate, consistent product information, then use the differences between systems and markets to find where the problems are.
- If the system struggles to explain the product, improve attribute precision, use-case clarity and claim evidence.
- If shopping information is weak or wrong, check feeds, Merchant Center, price, availability, variants and merchant mappings.
- If systems that cite sources favour competitors, check the third-party evidence around those products before publishing more content on your own site.
- If warnings appear, trace the exact claim, ingredient, certification or safety statement behind the caution and verify whether the evidence is product-specific.
- If results change by language or market, investigate local retailers, reviews, availability, product naming and evidence rather than assuming the English answer will transfer.
- If repeated runs vary a lot, record the differences and retest before assuming a website, content or feed change caused them.
What ecommerce brands can realistically improve
No brand can force an AI system to recommend a product. But ecommerce teams can improve the product information and evidence those systems can find and use.
1. Product data and attributes
Make the product easy to identify and compare. Titles, descriptions, identifiers, variants, specifications, size, material, ingredients, compatibility, intended use and other category-relevant attributes should be precise and current.
OpenAI’s current commerce documentation says structured product feeds help ChatGPT index products, understand core attributes and present accurate information. Its product-feed specification requires core fields such as product ID, title, description, link, image, availability, price and brand, with additional fields available for richer product detail. OpenAI product feeds Feed specification
The practical point is simple: good catalogue data matters. The documentation does not show that any one field guarantees a recommendation.
2. Product-page clarity
A product page should answer the questions a buyer and a machine need to resolve. What is the product? Who is it for? Which problem does it solve? Which variant is relevant? What are the constraints, exclusions or trade-offs?
Generic marketing claims are weak comparison material. Specific, supported statements give AI systems more usable information when a recommendation depends on fit.
3. Consistency across website, PIM, Merchant Center, retailers and marketplaces
Conflicting product information creates avoidable ambiguity. Check whether title, size, ingredients, specifications, price, stock, shipping, claims and identifiers stay consistent across your website, PIM, Merchant Center, retailers and marketplaces.
For Google, merchant listing structured data can make product pages eligible for richer merchant experiences and can communicate details such as price, availability, shipping and returns. It is useful infrastructure, not a guarantee of recommendation inside an AI answer. Google merchant listing structured data
4. Claims and supporting evidence
Claims become commercially important when they help the system distinguish one product from another. ‘Dermatologically tested’, ‘recycled material’, ‘clinically proven’, ‘Made in Italy’, ‘suitable for sensitive skin’ or a performance claim may affect the comparison only if the wording, scope and evidence are clear enough to use responsibly.
The practical task is not to add more claims. It is to make important claims precise, consistent and supportable, with evidence that matches the product and market.
5. Reviews and independent evidence
OpenAI’s current product-discovery and shopping-research documentation says results may use merchant product data, publicly available product information and other relevant retail sources. OpenAI product results OpenAI shopping research
For brands, their own website is only part of the information available to an AI system. Reviews, specialist retailers, editorial comparisons, recognised certifications and other credible external sources can help systems confirm or challenge what the brand says.
6. Competitive differentiation
A product with complete technical data can still lose because another product fits the buying need better. Look at the attributes and evidence that repeatedly help competitors win: price point, formulation, material, delivery, warranty, certification, use-case fit, retailer coverage or another commercially relevant factor.
The goal is not to copy the competitor. It is to understand whether your real differentiation is explicit enough to be used in a comparison.
7. Availability, price and market information
Recommendations can become inaccurate quickly when price, stock or merchant information is out of date. OpenAI notes that prices can come from third-party providers and may lag merchant changes. Its merchant selection can consider factors such as availability and price. OpenAI product-result documentation
Keep availability, price, variant and merchant information as current as possible. When the price, stock or merchant route is wrong, the problem is not only visibility. The commercial information itself is wrong.
8. Language and local-market evidence
For European brands, do not assume that a strong English product record will behave the same way in Spanish, Italian, German or French buying situations. Product naming, retailer coverage, reviews, certifications, availability and locally relevant sources change by market.
This is also where literal translation is insufficient. A customer in Spain or Italy may describe the same need differently, expect different proof or see a different competitor set.
9. Relevance to specific buying situations
A product is recommended for a specific need, customer, budget and set of constraints.
OpenAI states that product results are selected for relevance to the user’s intent and context, and that factors such as price or reviews can become more or less important depending on the request. That is why testing realistic buying situations matters. How ChatGPT selects product results
Why technical optimisation alone is not enough
Structured data, feeds and Merchant Center matter because they help systems read and understand product information. They are important parts of many ecommerce and AI commerce experiences.
But they are not the whole answer.
Google’s current AI Performance Insights are designed to show how brands appear across conversational shopping queries in Google’s AI ecosystem, including share of voice, terms, attributes and shopper intent. Google also recommends high-quality, up-to-date product data. The report is currently limited to English-language queries in selected markets, so European teams should not treat it as a complete multi-market measurement layer. Google AI Performance Insights
Google’s conversational product attributes go further by allowing merchants to provide optional information such as product Q&A, document links, related products and richer variant detail. Google describes these attributes as a complement to the primary Merchant Center product data specification, not a replacement for it. Google conversational attributes
These changes make product data more important. They still do not support a simple rule such as ‘add schema and recommendations will improve’.
AI systems can also use public web information, retailer content, reviews and other third-party sources. For products where trust matters more, third-party evidence may affect how easily the system can compare or support the product.
What to investigate when AI product recommendations go wrong
Start with the problem you can see. Do not jump straight to a generic optimisation checklist.
If the product is absent
- Is the product accessible and clearly identified on the brand site and relevant retailer and merchant sites?
- Are the attributes needed for this buying situation present and specific?
- Is price, availability and market eligibility current?
- Does the system have credible third-party or retail evidence for the product?
- Does the query describe a need your product genuinely fits, or are competitors a better match?
If the product appears but is misrepresented
- Which fact is wrong: variant, feature, price, claim, ingredient, availability or intended use?
- Where does the incorrect information appear: on the website, in feeds, at retailers or in third-party sources?
- Is the same error repeated across systems or isolated to one platform and run?
- Can the correct fact be made clearer and more consistent at the source?
If competitors are repeatedly selected
- Which buying criteria are the systems using to justify the competitor?
- Are those criteria genuinely stronger for the competitor, or simply better documented?
- Does the competitor have stronger local retail coverage, reviews or independent evidence?
- Is your differentiation present at product level, or only in broader brand messaging?
If the system adds warnings or cautions
- Is the caution connected to a product claim, safety issue, ingredient, suitability statement or certification?
- Is the evidence product-specific, brand-level or unrelated?
- Can the system verify the claim against an authoritative or independent source?
- Is the warning valid, overly broad or factually wrong?
If purchase information is wrong
- Compare current price, stock, variant and shipping information across the website, feed and merchant listings.
- Check whether an outdated retailer page is easier to access than the current first-party source.
- Check product identifiers and variant mapping.
- Separate a recommendation problem from a merchant-data or checkout problem.
If performance differs by language or market
- Compare local product pages, Merchant Center data, retailer listings, reviews and claims.
- Check whether the product is genuinely available and competitively priced in each market.
- Review the local-language sources the system uses or cites where available.
- Test the same buying need with natural local phrasing rather than translated prompts only.
If repeated runs vary a lot
- Do not average meaningful variability away.
- Record which products appear and disappear from the shortlist.
- Compare the reasons, sources and warnings attached to each outcome.
- Retest before attributing the difference to a website or data change.
Why European market and language differences matter
A European ecommerce brand rarely has the same information available in every market. The product may have one first-party page in English, another in Italian, different retailers in Spain, different review volume in Germany and different certification or claim language by market.
That means AI product visibility can vary from one market to another. The system may find a different product name, retailer, price, stock position, set of reviews or source mix.
For a multi-market brand, ‘How visible are we in AI?’ is too broad. A more useful question is: how does this product perform for this buying situation, in this market and language, against these competitors?
Measure and retest after the fix
Once you know what needs fixing, change the information or evidence you control and run the same buying situations again.
At minimum, record whether the product was visible, represented correctly, recommended, selected and able to progress towards purchase. Keep the evidence from each run so you can see whether a change is real or just normal variation.
This article stops there because measurement needs its own treatment. Comparing systems, markets and repeated runs over time requires a separate method.
Our practical guide to auditing AI commerce visibility takes you through that process, from preparing buying questions to analysing findings and retesting corrections.
Find out why your products are being missed, described incorrectly or passed over
Lex Agentica’s AI Commerce Visibility & Selection Audit tests how priority products are discovered, represented, recommended and selected across real buying situations, systems, markets, languages and competitors. The goal is not more mentions. It is to show the team what needs fixing and what should be tested again.
The commercial bottom line
Improving AI product recommendations is not one optimisation task. It depends on product data, third-party evidence, competitive fit, market context and the systems that carry that information towards a purchase.
Start with the buying situation and the problem you can see. Fix the product data, evidence or market inconsistency that the evidence supports. Then retest.
If you cannot explain why a product is absent, described incorrectly or repeatedly passed over, the first job is to understand the cause before deciding what to optimise.
FAQ
How do I get my products recommended by ChatGPT?
There is no documented formula that guarantees a ChatGPT recommendation. Start by making product information accurate, specific and current; keep price and availability reliable; strengthen relevant third-party evidence; and test real buying situations to see where the product is absent, described incorrectly or passed over.
Does structured data improve AI product recommendations?
Structured data can help systems understand product information and can make pages eligible for Google merchant listing experiences. Treat it as useful product data infrastructure, not as a guarantee of better AI recommendations.
Does Merchant Center matter for AI visibility?
Merchant Center matters for Google’s commerce ecosystem because it supplies structured product information and now includes AI Performance Insights and conversational product attributes. It does not explain or control every form of AI visibility across other systems.
Why does an AI system recommend a competitor instead of my product?
A single answer cannot establish the cause. The difference may involve relevance to the buying situation, product attributes, evidence, reviews, availability, price, market context, source accessibility or model variability. Look for the same pattern across repeated tests before deciding what to change.
Should we optimise separately for each AI platform?
Start with accurate, consistent product information rather than separate tricks for each platform. Tools such as Merchant Center or OpenAI product feeds may still matter, but the core product details, claims, availability and market information should stay consistent.